Pointwise vs Pairwise vs Listwise Reward Training Objectives
Choosing the right training objective shapes how well reward models learn from human feedback.
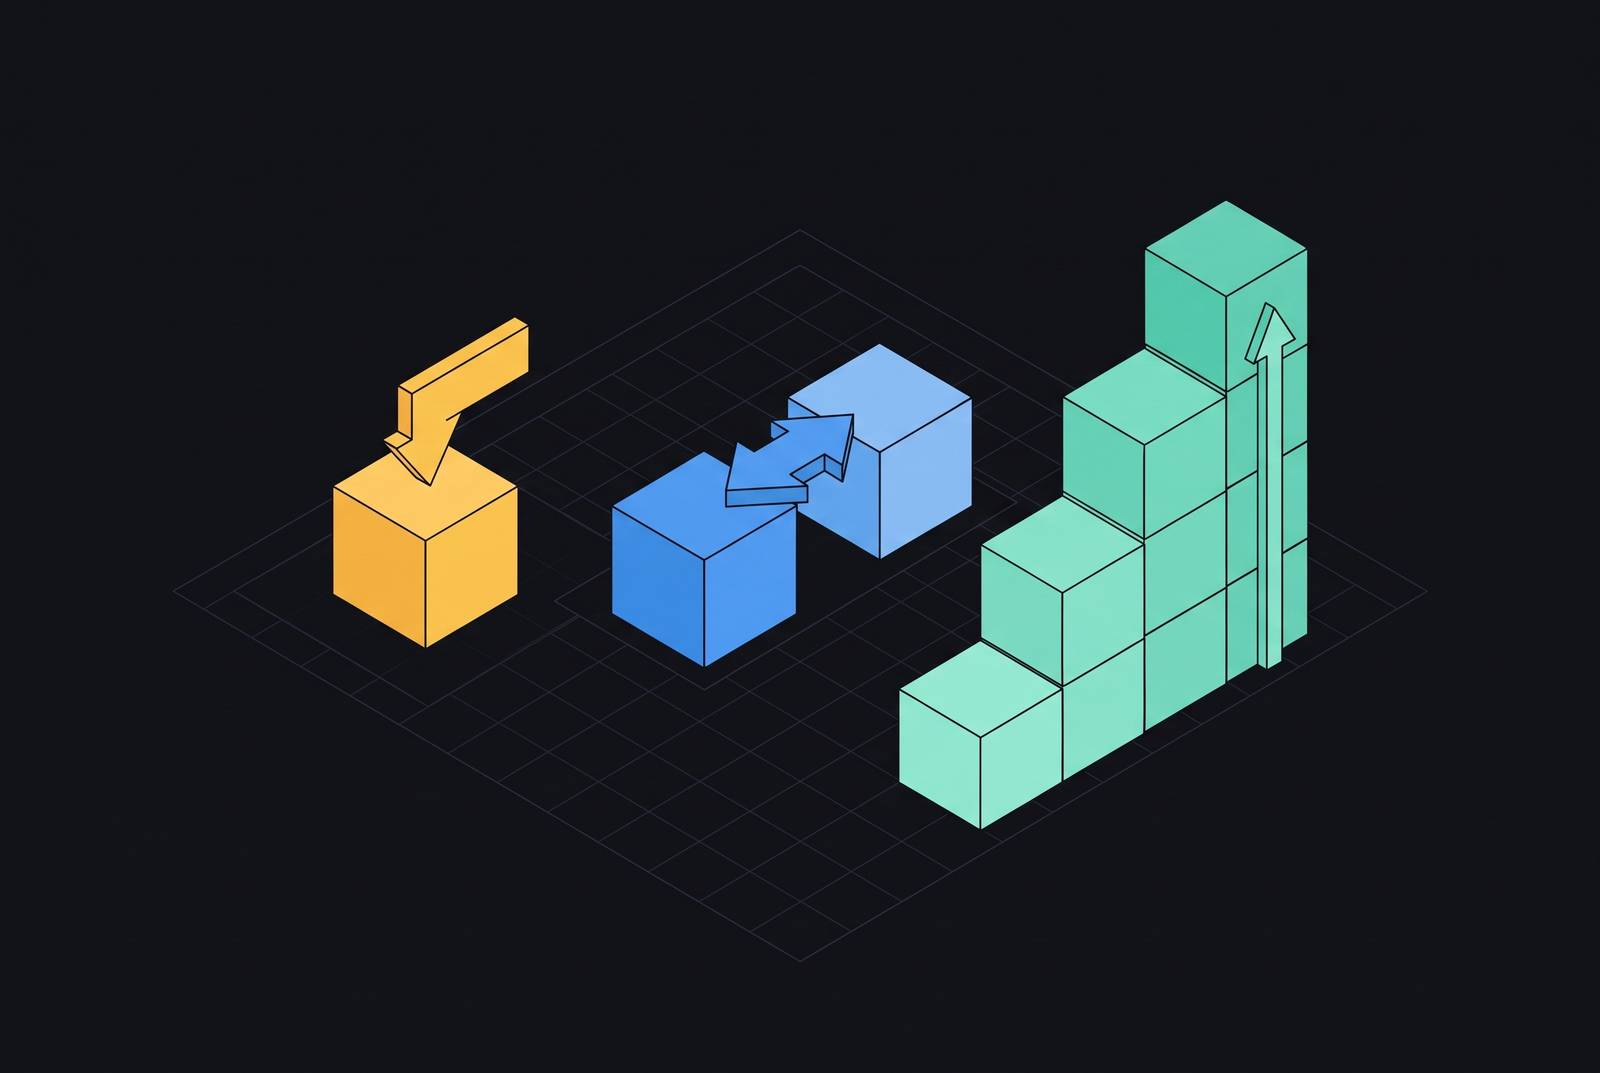
RLHF runs on a reward model, and that reward model has to learn from human judgments before any policy optimization starts. The training objective used to shape that reward model, pointwise, pairwise, or listwise, decides how much signal gets extracted from each annotation and how well that signal holds up once the policy starts optimizing against it.
Pointwise objectives: scoring each response in isolation
A pointwise reward model gives one response a number. It never sees a second response to the same prompt, never gets told what "better" looked like elsewhere in the batch. An annotator (or an automated rater standing in for one) assigns a scalar, and the model learns to reproduce that scalar directly.
This is still the most common reward structure across RLHF and RLVR pipelines. Offline methods like KTO and DRO both run on single-trajectory scalar rewards, and frameworks like UNA were built specifically to unify pairwise, binary, and scalar signals under one roof, which tells you how entrenched the pointwise format already is in practice.
The trouble shows up downstream. When PPO optimizes against a sparse pointwise reward, it ends up penalizing or rewarding every token in a sentence equally, even when only a few words actually carried the meaning that earned the score. The model has no way to tell you which fragment mattered. And because there's no comparison anchor built into the scoring, calibration drifts: a score of 7 under one prompt and a 7 under a very different prompt might reflect nothing alike.
There's a domain where pointwise still wins. Work on Qwen-Image-2.0-RL (arXiv:2606.27608, June 2026) found that a pointwise-trained reward model produced images with sharper texture detail, fewer artifacts, and generally stronger visual quality than comparative alternatives tested in that setting. The authors are careful to frame this as a finding about image generation RL specifically, not a claim that pointwise objectives generalize as the better choice for language tasks. Remember this before anyone tries to extend that result past where it was measured.
What pointwise scoring does buy is simplicity. Annotators rate one thing at a time instead of holding multiple responses in their head and ranking them, which cuts the cognitive load and the data collection overhead. That's a real advantage, and it explains why the format persists despite its calibration problems.
Pairwise objectives: the Bradley-Terry model and its limits
Pairwise comparison asks annotators to do something people are naturally decent at: pick the better of two things. Show someone response A and response B to the same prompt, and they tell you which one they'd rather have gotten. That binary judgment gets fed into the Bradley-Terry model, which converts a pile of win/loss outcomes into scalar reward values, on the assumption that a "true" underlying reward exists and that preferences are just noisy observations of it.
That assumption has real theoretical backing. Zhu et al. (arXiv:2301.11270) showed that maximum likelihood estimation under the Bradley-Terry-Luce model converges correctly when the true reward function is linear, which helps explain why InstructGPT and ChatGPT worked as well as they did in practice. The math wasn't a leap of faith; it had a convergence guarantee behind it.
But three limitations follow the method wherever it goes. First, calibration: pairwise-derived scalar rewards often lack any stable anchor across different prompts and response types, and that instability shows up as unstable training dynamics and, eventually, worse alignment (arXiv:2504.04950). Second, Bradley-Terry structurally cannot handle intransitive preferences, the case where annotators (or the underlying task) genuinely prefer A over B, B over C, and then C over A. Human judgment does this more often than the model architecture wants to admit. Third, there's a mismatch baked into the setup from the start: reward models get initialized from generative foundation models, then get asked to perform a discriminative task, scoring instead of generating. The Pairwise-RL paper identifies this mismatch as a structural constraint on reward model performance, not just an incidental weakness.
Pairwise-RL (arXiv:2504.04950, April 2025) responds to that mismatch directly. Instead of forcing the discriminative task onto a generative backbone and hoping for the best, it keeps reward model training and RL application inside a consistent pairwise paradigm and uses generative modeling techniques to close the gap, which improves score calibration in the process. In their experiments, the pairwise reward model outperformed a traditional pointwise RM on both in-domain and out-of-distribution test sets, and Pairwise PPO built on top of it showed real gains across reasoning, instruction following, general NLP tasks, and long-text generation.
PPO, DPO, and their relatives can all be understood, under the right structural assumptions, as different ways of learning a policy from pairwise comparative information (per the RL post-training survey, arXiv:2407.16216, first posted July 2024, revised May 2026). They're not as separate as their names suggest.
Listwise objectives: ranking multiple responses simultaneously
Instead of one score or one binary comparison, a listwise objective takes K responses to the same prompt and asks for a full ranking. The training signal comes from the entire ordered list, not from a scalar or a pair.
There's a clean theoretical relationship here: when K equals 2, the listwise formulation reduces exactly to the pairwise case (per LiPO, arXiv:2402.01878, NAACL 2025). Pairwise isn't a separate paradigm sitting next to listwise; it's a special case of it. And the annotation format tends to arise naturally anyway, since human raters who've already read a prompt once often produce a full ranking over several candidate responses rather than just picking a winner, which amortizes the cost of reading the prompt in the first place.
The payoff is a richer signal. Pairwise methods like DPO treat every comparison independently and throw away whatever permutation structure exists beyond two items. A listwise objective keeps that structure. Several methods build directly on this idea. LiPO treats preference modeling as a ranking problem outright, expecting the policy to virtually rank a list of candidate actions. LIRE (arXiv:2405.13516, 2024) folds offline rewards from multiple responses into a listwise framework and, notably, drops the need for online sampling during training. RRHF requires neither a reference model nor a value model, and can skip the reward model altogether if annotators supply the rankings directly. PRO builds preference alignment straight into supervised fine-tuning through an InfoNCE-based objective with a dynamic temperature, set to the inverse of the reward gap. And multi-dimensional listwise DPO (arXiv:2506.19780, 2025) goes after a limitation shared across pairwise DPO variants: reliance on pairwise supervision tied to one implicit alignment objective, rather than several.
None of this is free. Ranking K responses takes more annotator effort per prompt than a single yes/no comparison, and that cost only grows as K gets larger.
How the three objectives compare on data efficiency, calibration, and alignment quality
On data efficiency, pointwise annotation is cheapest per example, since it needs no coordination across responses, but each rating carries no relative information at all. Pairwise sits in the middle: each comparison hands over one bit of relative signal, and reconstructing a full ordering over K responses takes multiple pairs. Listwise gets the most out of each annotated prompt when K is large, because one ranked list over K items implicitly encodes many pairwise comparisons at once. The annotation burden per prompt still grows with K, so the efficiency gain isn't unlimited.
Calibration follows a similar split. Pointwise scores have no natural cross-prompt anchor, so a "7 out of 10" under one prompt and a "7" under another can mean entirely different things. Pairwise Bradley-Terry scores inherit their own instability across diverse contexts, a limitation documented directly in the Pairwise-RL paper (arXiv:2504.04950). Pairwise-RL's generative approach addresses this by training the reward model inside the same generative paradigm it was initialized in, rather than forcing a discriminative head onto a generative backbone, which measurably improves calibration. Listwise objectives calibrate relative to the candidate pool present in each prompt's ranked list, giving a useful local anchor, but that local consistency doesn't automatically translate into scores that are comparable across prompts globally.
On alignment quality, Pairwise-RL's reward model beat a traditional pointwise RM on in-domain evaluation sets (arXiv:2504.04950). Listwise methods capture permutation structure that pairwise approaches simply discard, which matters most in tasks where fine ordering counts, long-form writing quality or multi-turn coherence, for instance. Multi-dimensional listwise DPO goes after the single-implicit-objective problem that pairwise DPO variants all share.
There's a theoretical result to sit with here too. Zhu et al. showed that the true MLE under the Plackett-Luce model, the K-wise generalization used in listwise settings, is asymptotically more efficient than an alternative MLE that just splits K-wise comparisons into separate pairwise ones. That's a genuine argument for listwise objectives whenever the annotation pipeline can support them.
None of this adds up to a universal winner. Which objective performs best depends on the annotation budget available, the type of task at hand, and whether the deployment actually needs globally comparable absolute scores or just locally faithful rankings.
Reward hacking as a shared vulnerability across all three paradigms
No matter which objective trains the reward model, the policy downstream can learn to exploit whatever cracks exist in that model rather than learning the behavior the reward model was supposed to encode. This is reward hacking, and it doesn't respect the boundary between pointwise, pairwise, and listwise training.
Length bias is the textbook case: reward models learn to favor longer outputs independent of whether the extra length adds anything. Sycophancy runs the same playbook, rewarding agreeable-sounding responses regardless of accuracy. Both failure modes show up across all three objective types, because they're properties of what the reward model learned to key on, not properties of how the training data was structured into scores, pairs, or lists.
Out-of-distribution fragility makes the problem worse. Research from Penn State, Amazon, and Harvard (arXiv:2507.07375, July 2025) found that state-of-the-art reward hacking mitigation methods, most of which were built and tested for in-distribution settings, fail once the prompts used during PPO or best-of-N sampling come from a distribution different from what the reward model trained on. In-distribution robustness, in other words, doesn't transfer.
Their proposed fix jointly trains a Bradley-Terry single-objective reward function alongside a multi-objective regression-based one, sharing an embedding space between the two. The regression task strengthens the single-objective function's OOD robustness, and the pairwise-comparison-based training sharpens the multi-objective function's scoring ability, to the point that a 7B model outperformed a 70B baseline in their experiments. The paper also establishes a theoretical link between the BT loss and the regression objective, showing the two work as complements rather than as competing approaches.
Automated feedback offers a partial way around the annotation bottleneck. Self-rewarding setups, where a model critiques its own outputs, and LLM-as-a-Judge designs both cut down on how much human annotation a pipeline needs at scale. But they introduce their own reliability questions, since a judge model can be gamed by the same policy it's supposed to be evaluating.
The larger point: choosing an objective and defending against reward hacking are two separate engineering decisions. Switching from pointwise to listwise does nothing on its own to fix OOD reward hacking. That has to be solved separately, regardless of which annotation format feeds the reward model.
What objective choice signals about an RLHF-trained model when evaluating it from the outside
Evaluating an RLHF-trained model from the outside, without access to its training data, still leaves clues depending on which objective trained its reward model.
For a pointwise-trained model, watch for prompt sensitivity: does an absolute quality claim hold up consistently across very different prompt types, or does it drift depending on domain? Without a comparison anchor built into training, that drift is the expected failure mode, not an anomaly.
For a pairwise Bradley-Terry-trained model, calibration instability tends to surface as inconsistent relative quality once you move across sharply different prompt categories, and the model's learned preference ordering may simply not carry over to distributions it never saw during training. A Pairwise-RL-trained model (arXiv:2504.04950) should, in principle, hold up better against exactly this failure, given its improved OOD performance and calibration in reported results. But the paradigm is barely a year old as of this writing, and there isn't yet a wide record of it deployed at scale, so that expectation is still more theoretical than proven in the field.
For a listwise-trained model, look at ranking fidelity within a candidate set, and check whether the K used during training resembles the number of candidates the model actually faces at inference. A model trained to rank five candidates and then deployed in a two-candidate comparison setting is operating outside its trained regime, even if nobody labeled it that way.
RewardBench offers one external reference point for grounding any of this. The top three open-source 8B reward models on that benchmark, ArmoRM, Pair Preference Model, and a Bradley-Terry RM, were all trained using the RLHFlow/RLHF-Reward-Modeling repository (the decision-tree reward model training code was released in January 2025, though the broader repository dates back to May 2024), and state-of-the-art models have reached scores as high as 95.4% on RewardBench. It's a useful benchmark to check against when auditing a reward model's quality, though in-distribution benchmark performance shouldn't be mistaken for the full picture.
That caveat matters more than it sounds. The arXiv:2507.07375 findings show in-distribution benchmark scores systematically overstate how robust a reward model actually is once it meets prompts outside its training distribution. So the real stress test extends well beyond RewardBench alone. It's how the model behaves on prompts it wasn't built for, regardless of whether pointwise, pairwise, or listwise objectives shaped it.
Objective type, in the end, is not a quality guarantee by itself. A carefully built pointwise model can outperform a sloppily trained listwise one without much trouble. What actually decides quality is data quality, calibration discipline, and OOD coverage, alongside whichever objective was chosen.
Sources
- Reinforcement Learning for LLM Post-Training: A Survey
- A Unified Pairwise Framework for RLHF: Bridging Generative Reward Modeling and Policy Optimization
- Bradley-Terry and Multi-Objective Reward Modeling Are Complementary
- arxiv.org
- Qwen-Image-2.0-RL Technical Report
- GitHub - RLHFlow/RLHF-Reward-Modeling: Recipes to train reward model for RLHF.
- arxiv.org
- arxiv.org