GRPO vs PPO for Large Language Model Fine-Tuning
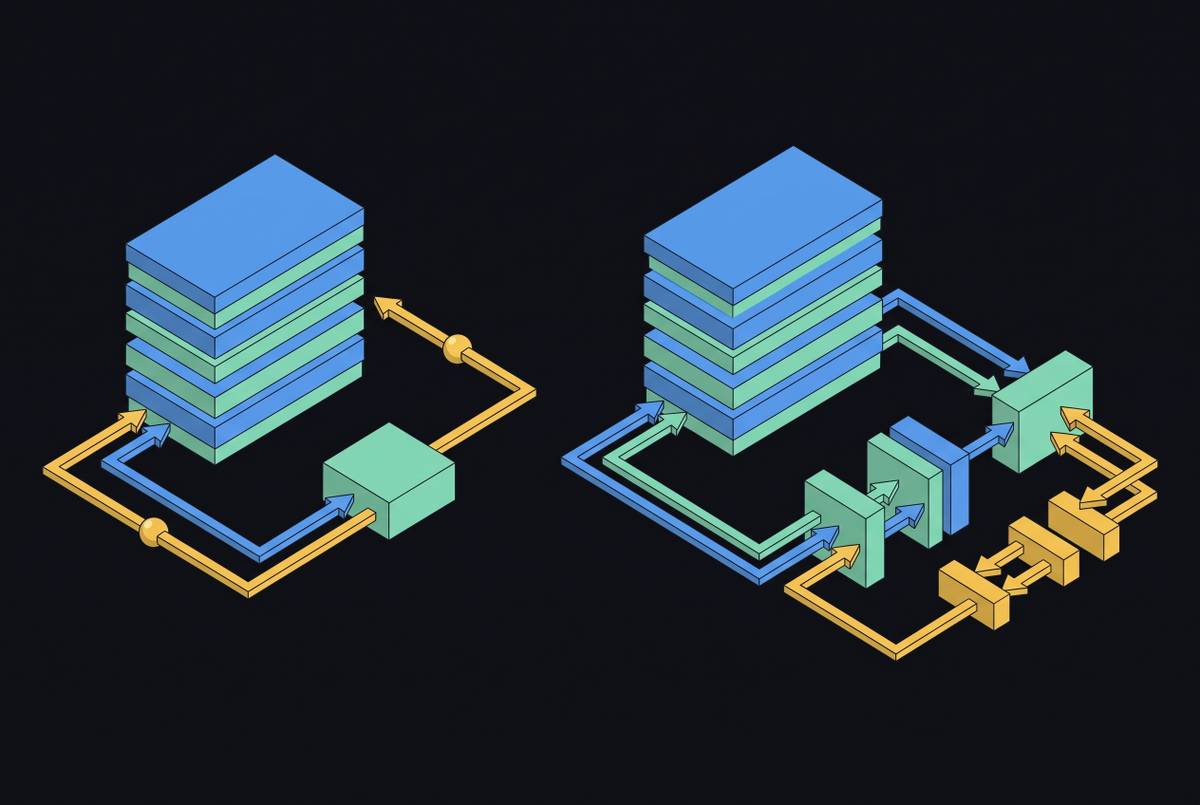
GRPO eliminates the critic model, cutting memory costs without sacrificing performance.
Devon Achterberg
Section
6 stories in Post-Training Pipelines.
GRPO eliminates the critic model, cutting memory costs without sacrificing performance.
Reward optimization in RL fine-tuning systematically erases previously learned capabilities.
Continuously updating preference data beats training reward models once on static data.
Rejection sampling matches reinforcement learning on math tasks without the complexity.
How to budget each RLHF stage separately before costs spiral.
The field is discovering that post-training stages must run in strict sequence, not interchangeably.