Reward Model Serving Latency in Online RL Training Loops
Faster reward scoring is worth nothing if it tanks the quality of training signals.
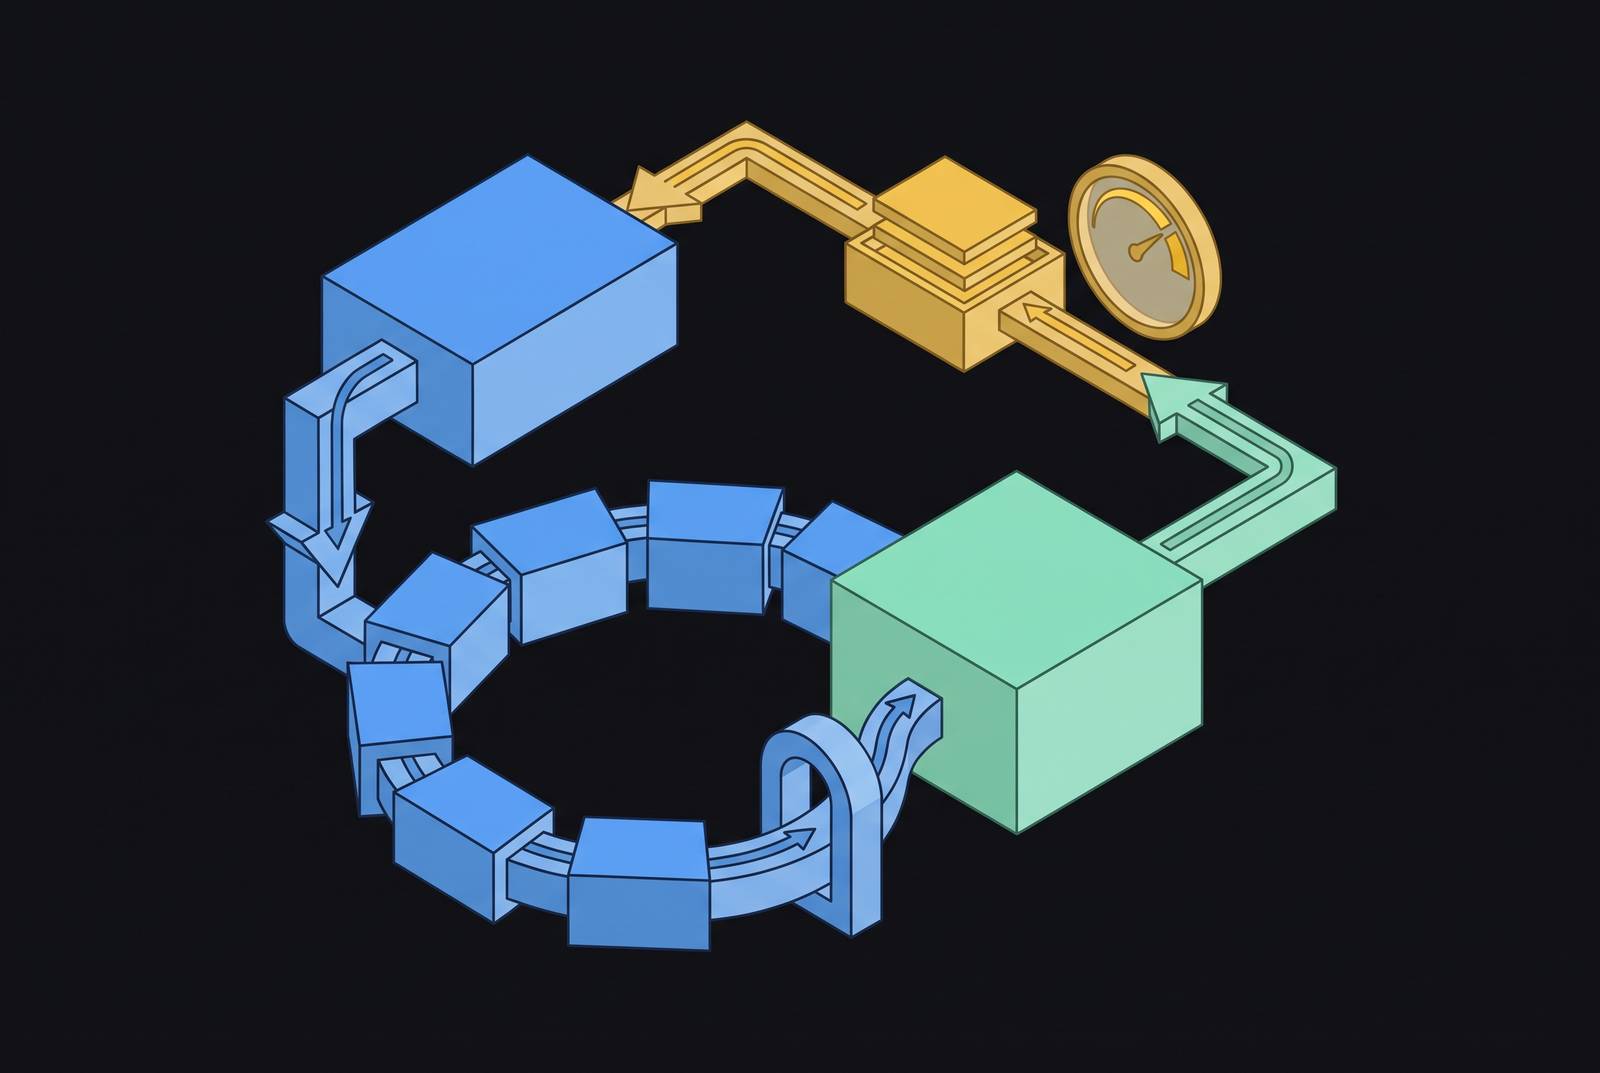
Reward model serving latency is a structural feature of how online reinforcement learning works: the reward model sits between the two most expensive phases of the training loop, and its slowness ripples through every iteration that follows.
Reward model serving latency is a structural problem
Online RL for large language models runs on a cycle of three interdependent phases: an actor generates rollouts, a reward or critic or reference model evaluates them, and the actor and critic weights get updated based on that evaluation. That sequencing is a logical requirement of the algorithm. It's a logical requirement of the algorithm: a gradient update needs a reward signal, and a reward signal needs a completed response to evaluate.
The consequence is that any delay in reward scoring converts directly into idle GPU time on the training side, a form of bubble inflation that has nothing to do with how well the training code is written. Inference, meaning rollout generation, already accounts for more than 90% of total runtime in online RL setups, and the reward model's share of that runtime is not a rounding error. It grows precisely as reward models get better at their job: the more useful a reward model becomes, the more expensive it gets to keep in the loop. That tension between reward model usefulness and reward model cost runs through everything else in this piece.
Dividing the compute budget between rollout generation and reward scoring
Before assigning blame to any single component, the baseline numbers matter. Autoregressive generation is the dominant consumer of wall-clock time in online RL, and a single rollout step for a large reasoning model can take tens of minutes, with long generation lengths pushing rollouts alone to roughly 70% of the compute spent inside the inference phase, setting the floor reward latency stacks on top of. Reward scoring cannot begin until a rollout completes, so rollout duration sets a lower bound on when reward evaluation can even start, and reward latency then stacks on top of that floor rather than hiding inside it.
Group-based algorithms like GRPO make the arithmetic worse. Multiple rollouts get generated per prompt, and every response in that group has to be scored before the algorithm can compute the group-relative advantage used in the update. The batch is gated by the slowest reward score in the group, a max-latency problem rather than a mean-latency problem, so outliers matter far more than they would in a typical throughput calculation.
Some of that compute is simply wasted. The HIVE paper documents that a large share of computational resources goes toward low-utility prompts that yield negligible gradients, so both the rollout compute and the reward compute spent on those prompts do nothing to move training forward. HIVE addresses this by filtering prompts before rollout generation using historical reward statistics and response entropy, achieving up to 2.3× total training speedup, evidence that reducing the number of reward evaluations is as powerful as speeding up each individual evaluation. Cutting the number of reward evaluations can matter as much as making each individual evaluation faster. Optimizing rollout speed alone, or reward speed alone, just moves the bottleneck to whichever one wasn't touched.
How generative reward models multiply scoring latency
Reward models did not get slower by accident. They got slower because they got more capable, and that trade is closer to a law of the domain than a design mistake anyone could have avoided.
Discriminative reward models are fast by construction: a linear head sits on top of an LLM backbone, one forward pass produces a scalar score, and there is no autoregressive decoding involved at all. The catch is capability. Per the RRC paper, discriminative reward models do not fully utilize the text generation capabilities of LLMs and consequently do not take advantage of instruction fine-tuning and explicit chain-of-thought reasoning, and this capability gap is described as a fundamental barrier rather than a practical inconvenience.
Generative reward models close that gap by producing a chain-of-thought critique before arriving at a judgment, but that critique is itself an autoregressive generation: the reward model now runs its own rollout with its own latency, stacked directly on top of the actor's rollout latency. Process reward models push the cost further still. Process Reward Models, which score every intermediate reasoning step rather than only the final output, multiply the problem further: scoring N steps per response requires N forward passes from the reward model, amplifying latency linearly with reasoning depth. That cost buys something real: PRMs give denser credit assignment and more stable policy learning than reward signals that only look at final outcomes, so the N-fold latency is the price paid for a genuinely better training signal, not overhead for its own sake.
Sampling makes the picture more complicated again. The inference-time scaling work behind DeepSeek-GRM shows that reward quality can be further increased by sampling multiple reward judgments in parallel through voting, but this multiplies latency again, with more samples meaning more compute and slower wall-clock time per training step. Reward fidelity and training throughput sit on opposite ends of a single dial. Moving toward more capable reward models means accepting a higher cost per evaluation, and no serving optimization changes that basic exchange rate.
Simplifying reward models to save time and its cost to training signal quality
Faced with that trade-off, one shortcut is to skip the learned reward model. Verifiable rewards, the rule-based checkers behind RLVR, return a scalar instantly with no model inference and no serving latency at all. This is why RLVR paired with GRPO became the dominant approach for training reasoning models through 2025, with Qwen3, MiMo, Mistral's Magistral, and Google's Gemma 3 all building RL stages around verifiable rewards for math and code. Where ground truth exists, this shortcut is close to free.
The constraint is that ground truth only exists in some domains. Instruction-following, writing quality, long-horizon planning, and general chat have no verifier to check against, so the reward has to come from a model, and model-based reward carries latency no matter how much anyone would prefer otherwise. Simplifying a learned reward model to save time on the wire doesn't sidestep that latency so much as introduce a new failure mode. Recent work documents three distinct exploitation patterns that occur when practitioners shrink learned reward models to cut evaluation time during online RL with generative rewards, including solution appending, where a model attaches a previously solved problem to fool the reward model despite the actual task failing outright, along with step inflation and related artifacts.
The RRC paper isolates a subtler version of the same trap. Forcing a generative reward model into scalar output, typically by reading off preference token probabilities to get something that looks like a fast scalar score, causes probability collapse once chain-of-thought reasoning gets involved in the reward judgment. The speed gained by squeezing a GenRM into scalar form comes directly out of the reasoning capability that made the GenRM worth using in the first place. Going offline doesn't offer a clean escape either. Purely offline methods like DPO and its variants show weaker performance than online approaches in both reward-model-based RL and RLAIF settings, so avoiding real-time reward serving by moving offline carries its own quality cost. Every direction that trims latency by simplifying the reward model trims something the training signal actually needed.
Async execution architectures and reward latency
Architecture offers a way out that algorithm design alone doesn't. If rollout generation, reward scoring, and the gradient update run as overlapping pipeline stages instead of a strict sequence, reward latency stops fully blocking the pipeline and becomes a throughput and queuing problem instead, which is a far more tractable class of problem to engineer around.
AsyncFlow implements exactly this as an asynchronous streaming framework for LLM post-training, decoupling the three phases so that reward scoring for one batch runs concurrently with rollout generation for the next. VeRL, the Volcengine RL framework adopted across multiple labs as production infrastructure, uses SGLang as its inference engine and processes different rollout trajectories independently and in parallel, which measurably improves inference throughput. Relax, a 2026 training engine described as having an omni-native design and async execution, achieves a speedup over veRL on smaller Qwen3 on-policy training and a further speedup over colocated execution on a larger Qwen3-Omni model, with all execution modes converging to the same reward level on Qwen3 models.
ReaL takes a distinct route: rather than statically standing up separate servers for each model, it dynamically redistributes LLM parameters across GPUs and adapts the parallelization strategy for each function call, generation, reward inference, critic inference, reference inference, and training individually, which cuts idle time and eases the memory pressure of keeping several large models resident at once. RLAX, built at Apple, attacks the problem from the hardware side, running identical RL workloads across TPU v5p inference clusters of increasing size and holding near-linear throughput scaling as inference capacity grows, effectively absorbing reward latency by keeping a larger pool of rollouts in flight at any given moment. RhymeRL takes yet another angle, using speculative decoding drawn from a prompt's previous-epoch responses along with distribution-aware scheduling to strip out GPU bubbles, which indirectly cuts down how often a fresh reward evaluation is even needed by reusing prefix-matched work already computed in earlier epochs.
None of these systems make reward latency disappear. Each one shrinks the fraction of wall-clock time that latency is allowed to block, through overlapping work, reallocating GPU memory on the fly, or calling the reward model less often for the same amount of training progress.
The real cost of switching to generative reward models
Architecture explains how latency gets absorbed. It doesn't answer what a practitioner actually pays when choosing a more capable reward model, and the RRC paper is one of the few sources that puts hard wall-clock numbers next to that question. Its authors ran controlled comparisons of reward model types inside a live RL training loop, tested against open-ended chat and reasoning benchmarks.
The training-time comparison is direct. A discriminative reward model completes training in 8.2 hours. Baseline RL with a generative reward model takes longer than that discriminative baseline, and RRC's self-competitive ranking variant (RRC-SCR) takes longer still than the generative baseline it builds on. Each step toward a more capable reward model costs additional wall-clock hours, and none of that extra time is disguised in these numbers.
What justifies the extra hours is the underlying diagnosis. RRC's authors trace the underperformance of naive generative reward models back to a structural mismatch: these models are naturally suited to comparative ranking, not scalar output, and forcing them to produce scalar scores through preference token probabilities triggers probability collapse once chain-of-thought reasoning enters the judgment. RRC's fix keeps the reward model in its natural mode. Self-competitive ranking compares responses against each other within a sampled group, while anchor-guided ranking compares each response against a fixed set of reference responses, and both approaches derive reward from relative preference rather than forcing an absolute scalar, recovering the GenRM's comparative strength while staying compatible with RL optimization.
The extra hours spent on RRC-AGR are not wasted time. They produce a policy that is meaningfully better than what the faster, cheaper alternatives deliver. What remains an open question for any given team is whether its task domain can justify that cost, and that answer depends heavily on whether a discriminative reward model or a rule-based verifiable reward is even a viable substitute in the first place. Where verifiable rewards apply, as in math and code, the extra hours may not be worth spending. Where the task is open-ended chat or long-horizon writing, they often are the only path to a policy that actually improves.
Inference-time scaling of reward models trades latency for quality
DeepSeek-GRM introduces a more flexible version of the same trade-off, one that turns reward quality into a lever adjustable during a training run rather than a decision locked in at model selection time. Its central insight borrows from test-time compute scaling on the policy side: sampling several reward judgments from a generative reward model and aggregating them through voting improves reward quality, the same way sampling multiple candidate responses improves a policy's output quality.
The method behind it, Self-Principled Critique Tuning, trains the reward model to generate its own evaluation principles adaptively and critique responses against them accurately, using online RL for the training itself. The resulting DeepSeek-GRM models scale more effectively with added inference compute than prior reward models do.
What this buys practitioners is a dial instead of a fixed switch. Early in training, a single sample per evaluation keeps latency low even though reward quality is correspondingly lower, and sample count can be increased later once the policy stabilizes and reward signal quality becomes the binding constraint on further gains. That flexibility comes with an explicit cost curve: each added sample multiplies reward model compute linearly, while the resulting quality gain flattens out well before the compute cost does, so practitioners need to know where a given workload sits on that curve before adding samples is worth the expense. This effect reaches beyond a single final judgment, too. Recent infrastructure research notes that reward model calls occur throughout generation itself, in step-level scoring, safety-aware scaling, and RM-guided search, not only at the end of a rollout, so inference-time scaling of process reward models multiplies latency at every one of those embedded call sites rather than just once per response.
Practical serving strategies that reduce reward model latency without sacrificing signal quality
Put together, the evidence points to three categories of latency reduction available to teams building these pipelines, and each carries a distinct signal-quality trade-off worth weighing on its own terms.
The first category cuts the number of reward evaluations rather than speeding up any single one. RhymeRL's reuse of prefix-matched work from prior epochs works on the same principle from a different angle, avoiding fresh reward calls where a close match already exists.
The second category leaves the number of evaluations untouched and instead overlaps their cost with other work. None of these systems compete against each other so much as attack the same seam from different points in the stack, infrastructure, scheduling, and memory management alike.
The third category accepts higher per-evaluation cost deliberately, in exchange for a training signal that a faster reward model cannot supply. RRC's ranking-based rewards and DeepSeek-GRM's inference-time voting both sit here, and both make the same underlying case: spending more time per reward evaluation is defensible when it produces a policy that a cheaper reward model could not have trained as well. Choosing among these three categories is not a matter of picking the fastest option by default. It comes down to which one matches the task domain, whether a verifiable reward is even available, and how much a team is willing to pay in wall-clock hours for a policy that a shortcut could not have produced.
Sources
- Inference-Time Scaling for Generalist Reward Modeling
- RLAX: Large-Scale, Distributed Reinforcement Learning for Large Language Models on TPUs
- Scaling RL - 2025 roundup and 2026 lookout - looking glass
- RRC: Unlocking Generative Reward Models in LLM Reinforcement Learning via Ranking-Based Reward Construction
- How Fast Can Reward Models Score? A Systems Study of C++ and PyTorch Inference Runtimes for RLHF
- RRC: Unlocking Generative Reward Models in LLM Reinforcement Learning via Ranking-Based Reward Construction
- Relax: An Asynchronous Reinforcement Learning Engine for Omni-Modal Post-Training at Scale
- Asyncflow: An asynchronous streaming rl framework for efficient llm post-training · Pith